Tesseract OCR: how it works and how to use it in Python
For developers and technical teams evaluating open-source OCR. It explains how Tesseract works and gives working code for the command line and pytesseract. It also covers the limits to plan around before you use it on business documents.

Key takeaways
- Tesseract is a free, open-source OCR engine under the Apache 2.0 license. It started at HP in the 1980s, was developed by Google from 2006 to 2018, and is now maintained by the open-source community.
- The current release is Tesseract 5.5.3 (July 2026). Since version 4 it uses an LSTM neural network that reads a whole line of text at a time. It recognizes more than 100 languages.
- In Python you call it through pytesseract (0.3.13). `image_to_string` returns text, and `image_to_data` returns word boxes with a confidence score for each word.
- Results depend heavily on preprocessing. Rescaling, grayscale, binarization and deskewing often decide whether a scan is readable.
- Tesseract returns text, not fields. It doesn't know which number is an invoice total, so business document workflows need extraction, validation and review on top of it.
On this page
- What is Tesseract OCR?
- How does Tesseract work?
- How to install Tesseract
- The settings that matter
- Using Tesseract from the command line
- Using Tesseract in Python with pytesseract
- Getting word and character boxes
- Limitations of Tesseract
- When to use Tesseract, and when not to
- Test it on your worst scan, not your best one
- Frequently asked questions
Tesseract OCR is a free, open-source engine that turns images of printed text into text a computer can read. This task is called optical character recognition, or OCR. Since version 4, Tesseract uses an LSTM neural network that reads a line of text at a time. It supports more than 100 languages. You can run it from the command line or call it from Python through the pytesseract wrapper.
What is Tesseract OCR?
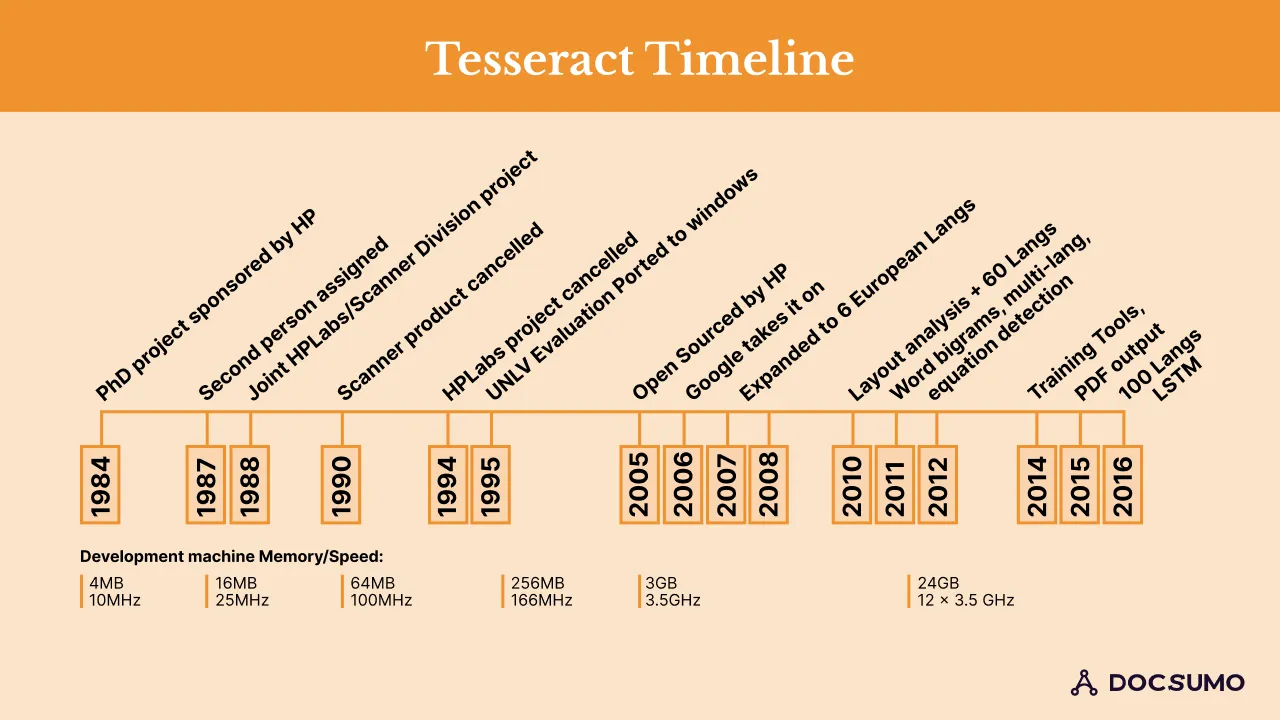
Tesseract began as a PhD research project at HP Labs in Bristol and was developed at HP between 1984 and 1994. HP released it as open source in 2005. Google developed it from 2006 until November 2018, and since then it has been maintained by open-source contributors. Tesseract 5.0.0 was released in November 2021; the latest release is 5.5.3, from July 2026.
Four things explain why developers still reach for it.
It's free
Tesseract is licensed under Apache 2.0, so you can use it commercially and modify the source.Language coverage
It recognizes more than 100 languages with ready-made models, and you can add or train more.Wrappers for most languages
pytesseract for Python, plus wrappers for Java, Go, .NET and others, save you from calling the C++ API directly.It runs anywhere
Linux, macOS and Windows, with no network call, which suits offline or air-gapped work.
How does Tesseract work?
Tesseract first analyzes the page layout to find blocks and lines of text, then passes each line to a recognition engine. It has two engines, the original legacy engine and, since version 4, an LSTM neural network.
- Scanned page
- Photo of a document
- Rendered PDF page
- 01Clean up the image
- 02Find blocks and text lines
- 03LSTM reads each line
- 04Language model picks the words
The legacy engine (Tesseract 3)
The original engine works in stages. It finds connected components, which are the pixel shapes that make up characters. It groups these shapes into blobs, organizes blobs into lines, and splits lines into words using the spacing between characters. It then recognizes words in two passes. Words recognized confidently in the first pass adapt the classifier, which then takes a second pass over the words it got wrong. A final step fixes spacing and small caps.
The LSTM engine (Tesseract 4 and later)
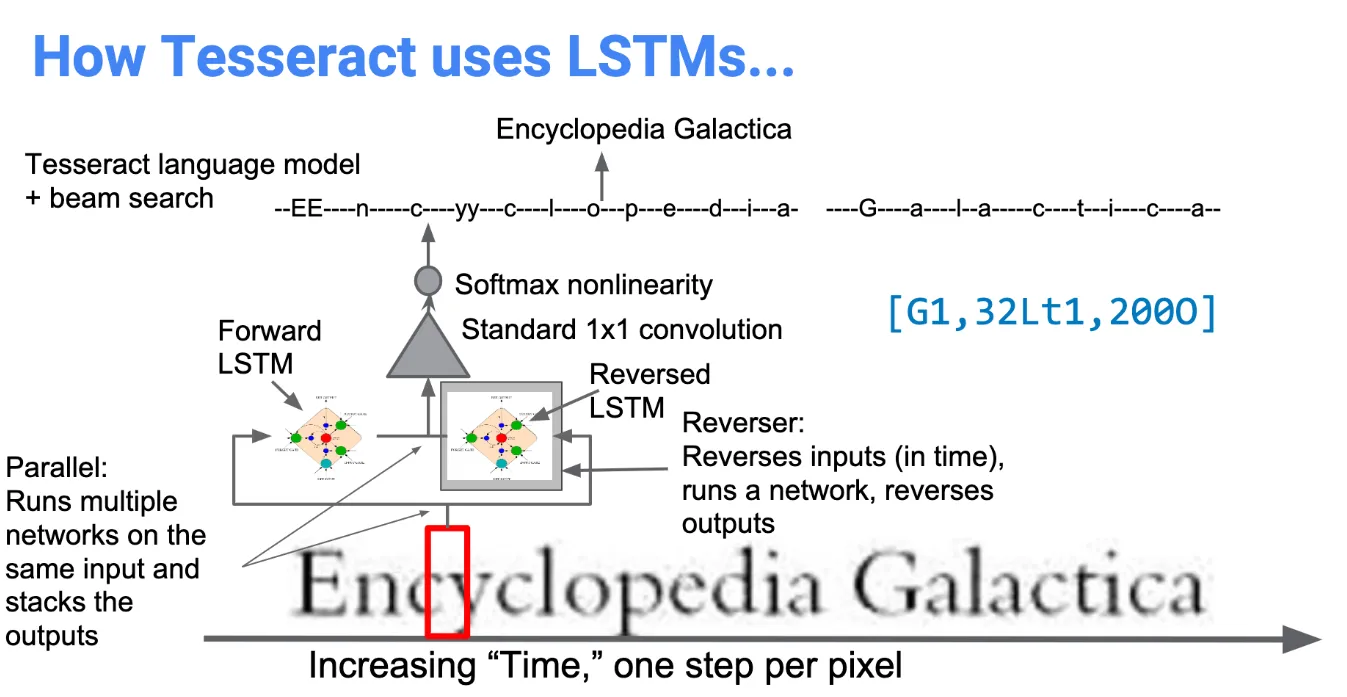
Since version 4, Tesseract's default engine is a long short-term memory (LSTM) network, a type of recurrent neural network that handles long sequences well. Instead of recognizing characters one by one, it reads each text line as a sequence. It moves across the image one pixel column at a time. A language model then picks the most likely words from the network's output, using a method called beam search. Tesseract still does its own page layout analysis first to find the lines to feed in.
How to install Tesseract
Setup takes four steps on any operating system. The commands for each follow.
- Install the engineUse your package manager on Linux, Homebrew on macOS, or the UB Mannheim installer on Windows.
- Check the installRun
tesseract --versionto confirm the binary is on your path. - Install the Python wrapperAdd pytesseract, plus OpenCV for loading and cleaning images.
- Add languages if you need themEach extra language is a separate trained-data file (see "Reading other languages" below).
Ubuntu or Debian:
sudo apt install tesseract-ocr
sudo apt install libtesseract-dev
macOS (Homebrew):
brew install tesseract
Windows: use the installers maintained by UB Mannheim (linked from the official installation guide), then add the install folder to your PATH.
Check the install:
tesseract --version
Then install the Python wrapper, plus OpenCV for image handling.
pip install pytesseract opencv-python
pytesseract only wraps the engine, so the tesseract binary must be installed first.
The settings that matter
Every Tesseract call takes a few key options.
| Option | Flag | What it does |
|---|---|---|
| Language | -l eng | Which trained model to use. Combine with +, for example -l eng+spa |
| OCR engine mode | --oem | 0 legacy only, 1 LSTM only, 2 both, 3 default (whatever is available) |
| Page segmentation mode | --psm | How to split the image into text. 3 (default) is fully automatic, 6 treats the image as one block of text, 7 as a single line, 11 finds sparse text |
There are 14 page segmentation modes (0 to 13). If you're reading a small crop, such as a single field, a mode like 6 or 7 usually works better than the default.
Using Tesseract from the command line
Write the text to ocr_text.txt.
tesseract test_image.jpg ocr_text -l eng --oem 1 --psm 3
Print it to the terminal instead.
tesseract test_image.jpg stdout -l eng --oem 1 --psm 3
Using Tesseract in Python with pytesseract
pytesseract accepts any image that Pillow or OpenCV can read. The basic call is image_to_string.
import cv2
import pytesseract

img = cv2.imread("test_image.jpg")
img = cv2.cvtColor(img, cv2.COLOR_BGR2RGB)  # OpenCV loads BGR; Tesseract expects RGB

config = r"--oem 1 --psm 3 -l eng"
text = pytesseract.image_to_string(img, config=config)
print(text)
Preprocessing improves results
Tesseract works best on clean, high-contrast, horizontal text at around 300 DPI. This restaurant receipt shows what happens without any cleanup.
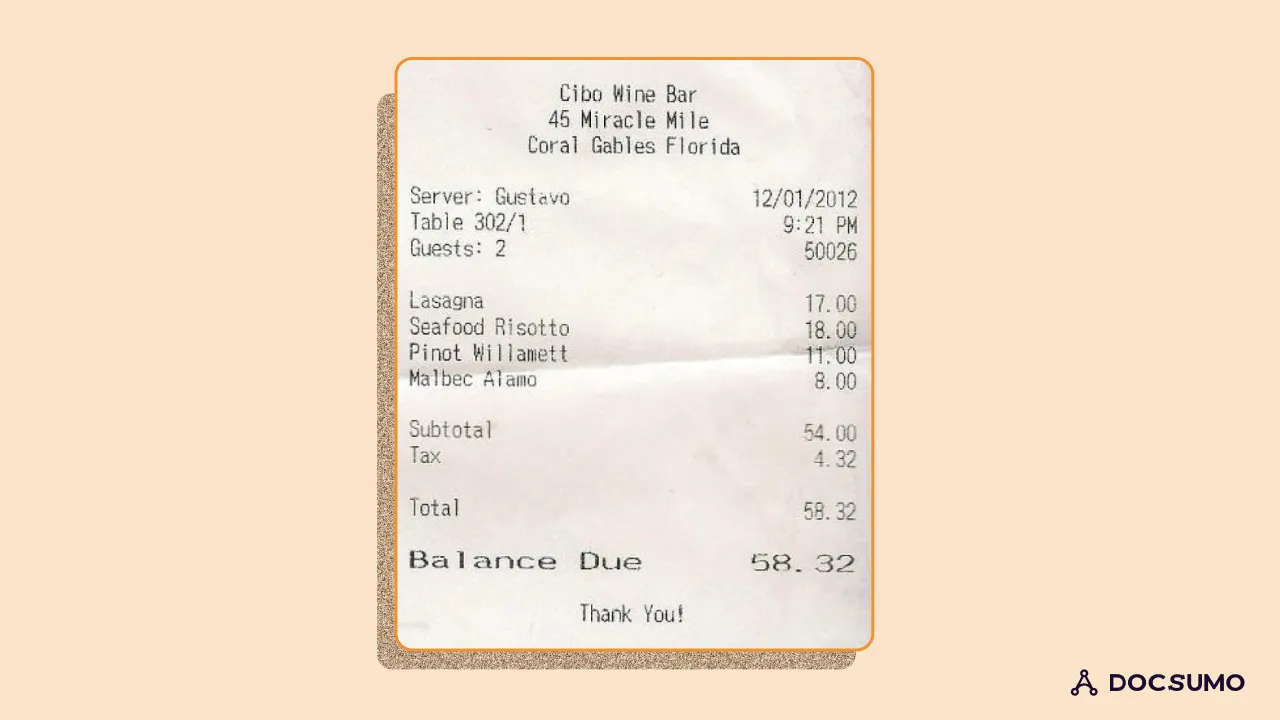
Run as-is with --psm 6, Tesseract reads most of it but gets several numbers wrong, including the subtotal, tax and total.
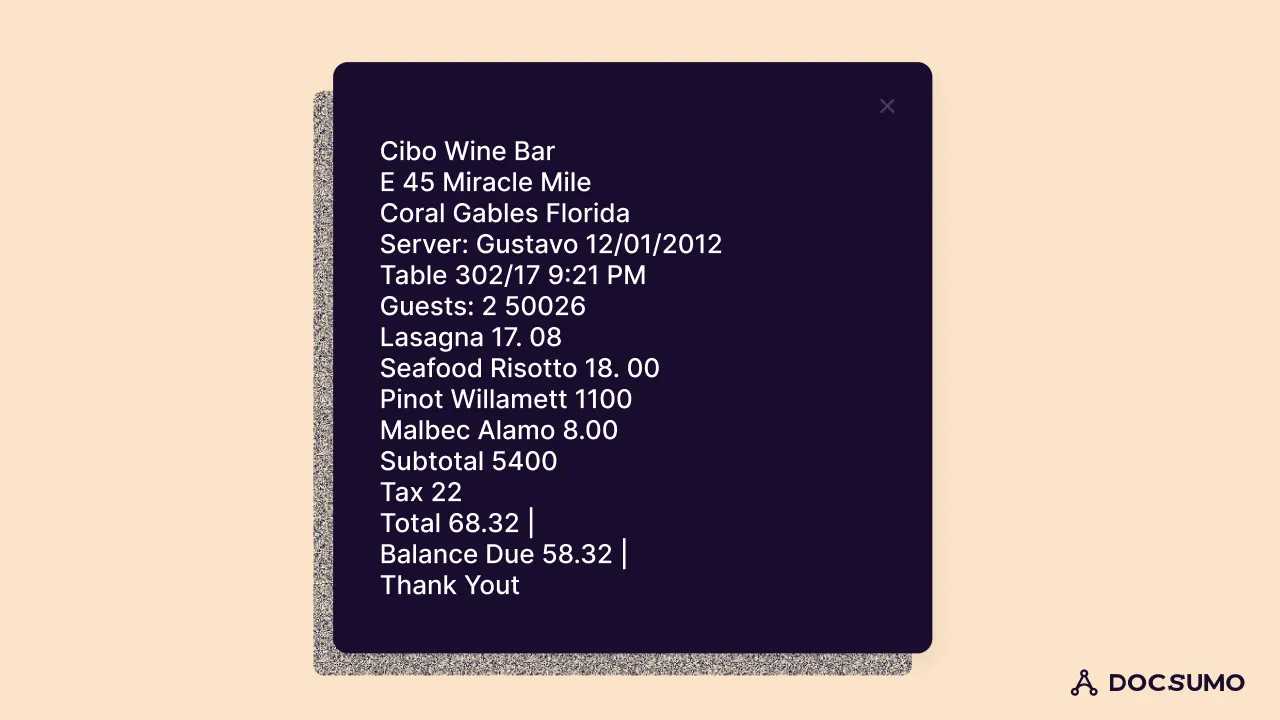
Two simple steps, upscaling and converting to grayscale, fix the subtotal and total.
img = cv2.imread("receipt.jpg")
img = cv2.resize(img, None, fx=2, fy=2, interpolation=cv2.INTER_CUBIC)
gray = cv2.cvtColor(img, cv2.COLOR_BGR2GRAY)
text = pytesseract.image_to_string(gray, config="--oem 1 --psm 6")
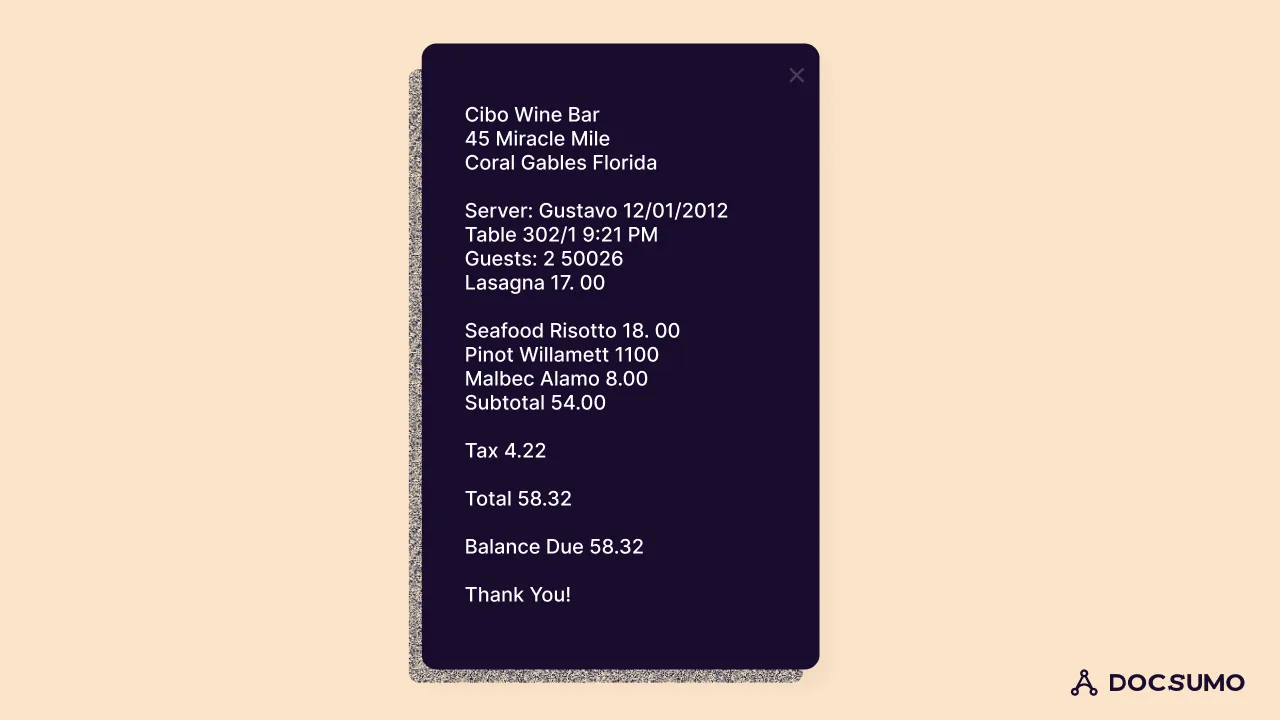
It's better, but still not right. The tax now reads 4.22 instead of 4.32, which is the core problem with OCR alone on financial documents. A misread digit looks like a valid number, so you need checks to catch it. For example, a check can test whether the subtotal plus tax equals the total.
The Tesseract docs list the preprocessing steps worth trying when output is poor.
- RescaleText that's too small or too large reads badly; around 300 DPI is the target.
- BinarizeConvert to black text on a white background so the engine sees clean shapes.
- Remove noiseSpecks and scanner grain get read as characters.
- DeskewRotate the page so lines are horizontal; skewed lines break line finding.
- Remove bordersDark scan edges can be mistaken for text.
Reading other languages
List the installed languages.
tesseract --list-langs
To add one, download its .traineddata file from the tessdata repository into your tessdata folder. On Homebrew this is typically /opt/homebrew/share/tessdata. You can also point TESSDATA_PREFIX at the folder.
export TESSDATA_PREFIX=/opt/homebrew/share/tessdata
Then pass the language code, or several joined with +.
text = pytesseract.image_to_string(img, config="-l spa --psm 6")
text = pytesseract.image_to_string(img, config="-l kan+chi_sim --psm 6")
Faster or more accurate models
Tesseract has three sets of trained models. Pick by whether you need speed, accuracy or the legacy engine.
tessdata_fast
8-bit integer models, the fastest, and the ones most Linux distributions ship. They can't be fine-tuned.tessdata_best
Float models, slower but more accurate, and the base for fine-tuning.tessdata
Includes the legacy engine models, needed for--oem 0or--oem 2.
Getting word and character boxes
To locate text on the page, not just read it, use image_to_boxes for characters or image_to_data for words.
Character boxes come first. Tesseract measures y from the bottom of the image.
import cv2
import pytesseract

img = cv2.imread("invoice.jpg")
height = img.shape[0]
boxes = pytesseract.image_to_boxes(img, output_type=pytesseract.Output.DICT)

for left, bottom, right, top in zip(boxes["left"], boxes["bottom"], boxes["right"], boxes["top"]):
    cv2.rectangle(img, (left, height - bottom), (right, height - top), (0, 255, 0), 2)

cv2.imwrite("invoice_char_boxes.jpg", img)
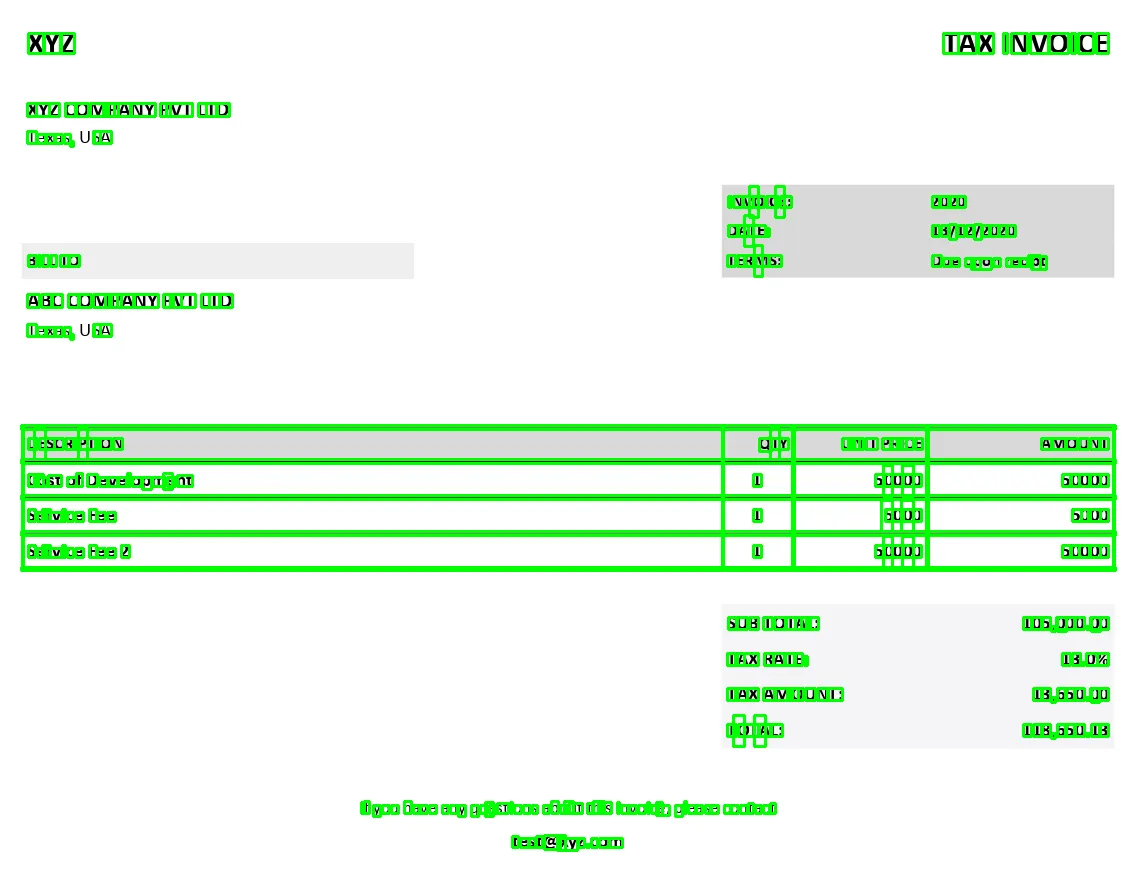
Word boxes come next, keeping only words with confidence above 70.
data = pytesseract.image_to_data(img, output_type=pytesseract.Output.DICT)
# keys: level, page_num, block_num, par_num, line_num, word_num,
#       left, top, width, height, conf, text

for i, word in enumerate(data["text"]):
    if word.strip() and float(data["conf"][i]) > 70:
        x, y, w, h = data["left"][i], data["top"][i], data["width"][i], data["height"][i]
        cv2.rectangle(img, (x, y), (x + w, y + h), (0, 255, 0), 2)

cv2.imwrite("invoice_word_boxes.jpg", img)
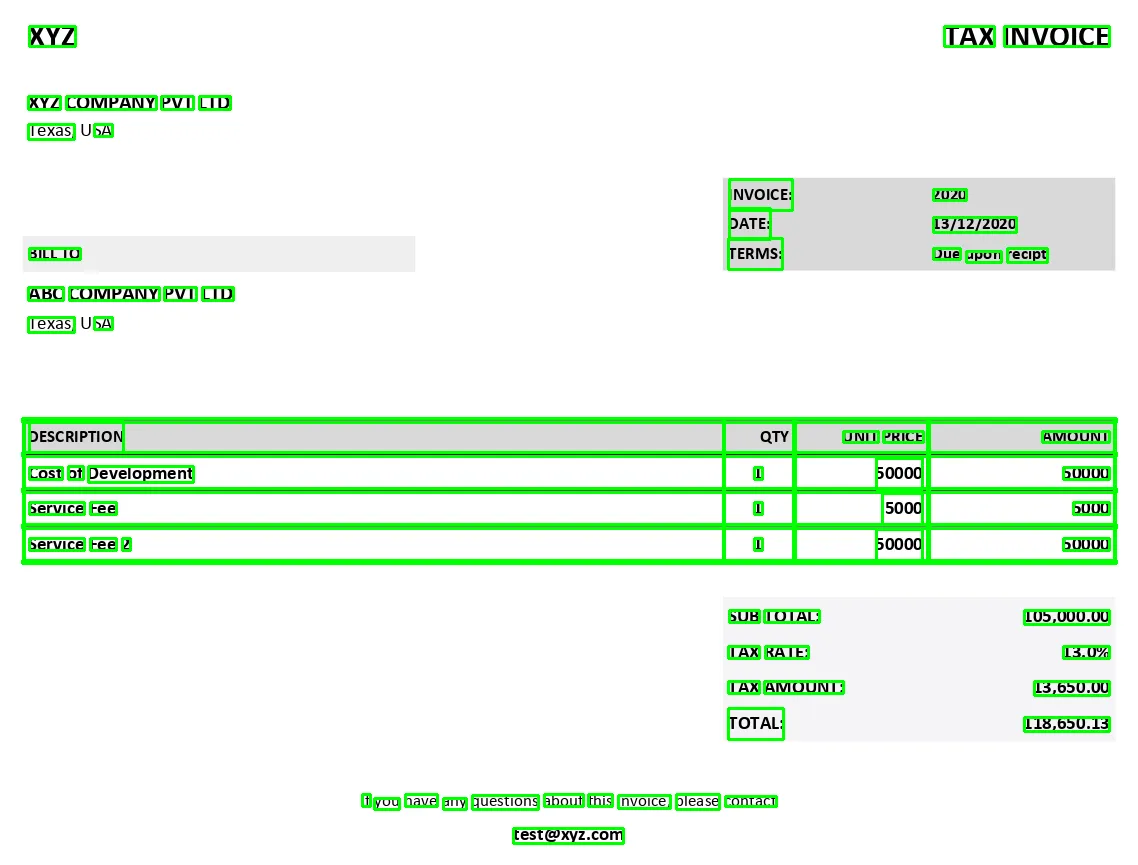
The confidence score is useful. Low-confidence words are the ones a person should check.
Limitations of Tesseract
In our experience running Tesseract alongside commercial engines, these limits show up most.
It depends on preprocessing
Results vary a lot with image quality, and the right cleanup differs by document. Good results take trial and error with modes, models and preprocessing.Scans and photos are hard
Skew, shadows, stamps and low resolution cause misreads.Complex layouts
Multi-column pages, forms and tables often come out in the wrong reading order.Handwriting
It's trained for printed text, so handwritten entries read poorly.Silent errors
It can return a wrong digit or gibberish with no warning beyond a lower confidence score.Text, not data
It doesn't know which value is the invoice number or the ending balance, and it doesn't rebuild tables.
When to use Tesseract, and when not to
Tesseract is a good fit for digitizing clean printed text, prototypes, offline processing, and projects where a developer can tune the pipeline. It's a weak fit when you need structured fields from varied business documents at volume. Examples are bank statements for underwriting and invoices for accounts payable. There you need a system that classifies documents, extracts named fields and tables, validates them and routes low-confidence values to a person. If that system has to run inside your own product, Docsumo's document extraction API provides it.
OCR alone
- A block of text per page
- Your code has to find the invoice number, total and line items
- A misread digit passes through as a valid number
- Every new layout means new parsing rules
OCR plus document processing
- Named fields and tables, as JSON
- Documents classified and fields labeled for you
- Totals checked against line items, with failures sent to a reviewer
- New layouts handled by models trained on many variations
That's what intelligent document processing adds on top of OCR. Docsumo reads printed and handwritten text, extracts fields and tables, runs validation checks and sends only the fields that fail a check to review.
- 99%field-level accuracy across 250+ document types
- 95%+of documents processed straight through, without manual review
For a deeper comparison, read IDP vs OCR or our guide to OCR APIs.
Test it on your worst scan, not your best one
We'd run any OCR engine on the files that will give it trouble before trusting it with the rest. Think a phone photo of a receipt, a long multi-page statement, or a page with handwriting mixed in. A clean, flat scan won't tell you much. The receipt above went through two cleanup steps and still misread the tax, and production documents are rarely that forgiving.
Tesseract is a sound starting point when you need free, offline OCR for clean printed text and have a developer to tune it. It returns text, not fields, so plan for that gap before you rely on it. If the goal is structured data from invoices, statements or forms at volume, put extraction and validation on top of it. You can also use a platform that includes OCR, extraction and validation.
Book a demo with a few of your own documents, or start a free trial.
Frequently asked questions
Is Tesseract OCR free for commercial use?
Yes. Tesseract is released under the Apache 2.0 license, which allows commercial use, modification and redistribution, provided you keep the license and notices.
What is the latest version of Tesseract?
Tesseract 5.5.3, released on July 24, 2026. Version 5.0.0 came out in November 2021, and the 5.x line keeps the LSTM engine introduced in version 4.
Is Tesseract good for handwriting?
Not really. Tesseract is trained on printed text, so handwritten documents usually give poor results. Handwriting needs a model built for it, such as the ones in commercial IDP platforms; Docsumo, for example, reads handwritten as well as printed text.
What is the difference between tessdata, tessdata_fast and tessdata_best?
They are three sets of trained language models. The tessdata_fast set uses 8-bit integer models that are faster and ship with most Linux distributions. The tessdata_best set uses float models that are slower but more accurate and can be fine-tuned. The tessdata set also includes models for the legacy engine.
Can Tesseract extract tables and fields from invoices?
It can return words with their positions, but it doesn't reconstruct tables or label fields. For invoices, bank statements and forms you need a layer that understands the layout, such as an intelligent document processing platform.