How to extract data from PDFs: 5 methods compared
For finance, lending and operations teams that receive invoices, statements and forms as PDFs: 5 ways to get the data out, how to get it into Excel or Google Sheets, and how to pick a method for your volume.

Key takeaways
- A PDF stores characters and their positions on the page, not fields, so software has to work out which text is the invoice number or the closing balance.
- The 5 main methods are manual entry, PDF converters, table extraction tools, rule-based templates and AI-based extraction. Volume and layout variety decide which one fits.
- Scanned PDFs have no text layer, so they need OCR (optical character recognition) before any extraction.
- Excel for Windows imports tables from a PDF (Data > Get Data > From File > From PDF). Google Sheets can't open PDFs, so get the tables into Excel or CSV first.
- For recurring business documents, look for validation and review, not just extraction. Totals should add up, and low-confidence fields should go to a person.
On this page
- Why extracting data from PDFs is hard
- First, check what kind of PDF you have
- 5 ways to extract data from PDFs
- How to convert PDF data to Excel or Google Sheets
- How to extract pages from a PDF
- Common PDF extraction failures and fixes
- How to automate PDF data extraction
- Checks to run on extracted PDF data
- The method that survives at your volume
- Frequently asked questions
To extract data from a PDF, you have 5 options. You can type it in by hand, convert the PDF to Excel or Word, use a table extraction tool, build a rule-based template for each layout, or use AI-based extraction that finds fields on any layout. Copying or converting works for a handful of files; invoices, statements and forms that arrive every day in many layouts need AI extraction with validation.
| Field | Extracted value | Read |
|---|---|---|
| Vendor name | Northeast Kitchen Equipment | |
| Invoice number | NKE-9921 | |
| Invoice date | 2026-08-12 | |
| Due date | 2026-09-11 | |
| Payment terms | Net 30 | |
| PO number | 5498 (handwritten) |
| Field | Extracted value | Read |
|---|---|---|
| Vendor address | 37 Bridge St, Westbrook, ME | |
| Bill to | Harbor Street Bakery LLC | |
| Ship to | 22 Thames St, Portland, ME | |
| Remit to | PO Box 3170, Portland, ME |
| Field | Extracted value | Read |
|---|---|---|
| Item code | WT-3072 | |
| Description | Stainless work table, 30 x 72 in | |
| Quantity | 2 | |
| Unit of measure | EA | |
| Unit price | 385.00 | |
| Amount | 770.00 |
| Field | Extracted value | Read |
|---|---|---|
| Subtotal | 23,250.00 | |
| Sales tax rate | 5.5% | |
| Sales tax | 1,278.75 | |
| Freight | 121.25 | |
| Total due | 24,650.00 |
Why extracting data from PDFs is hard#
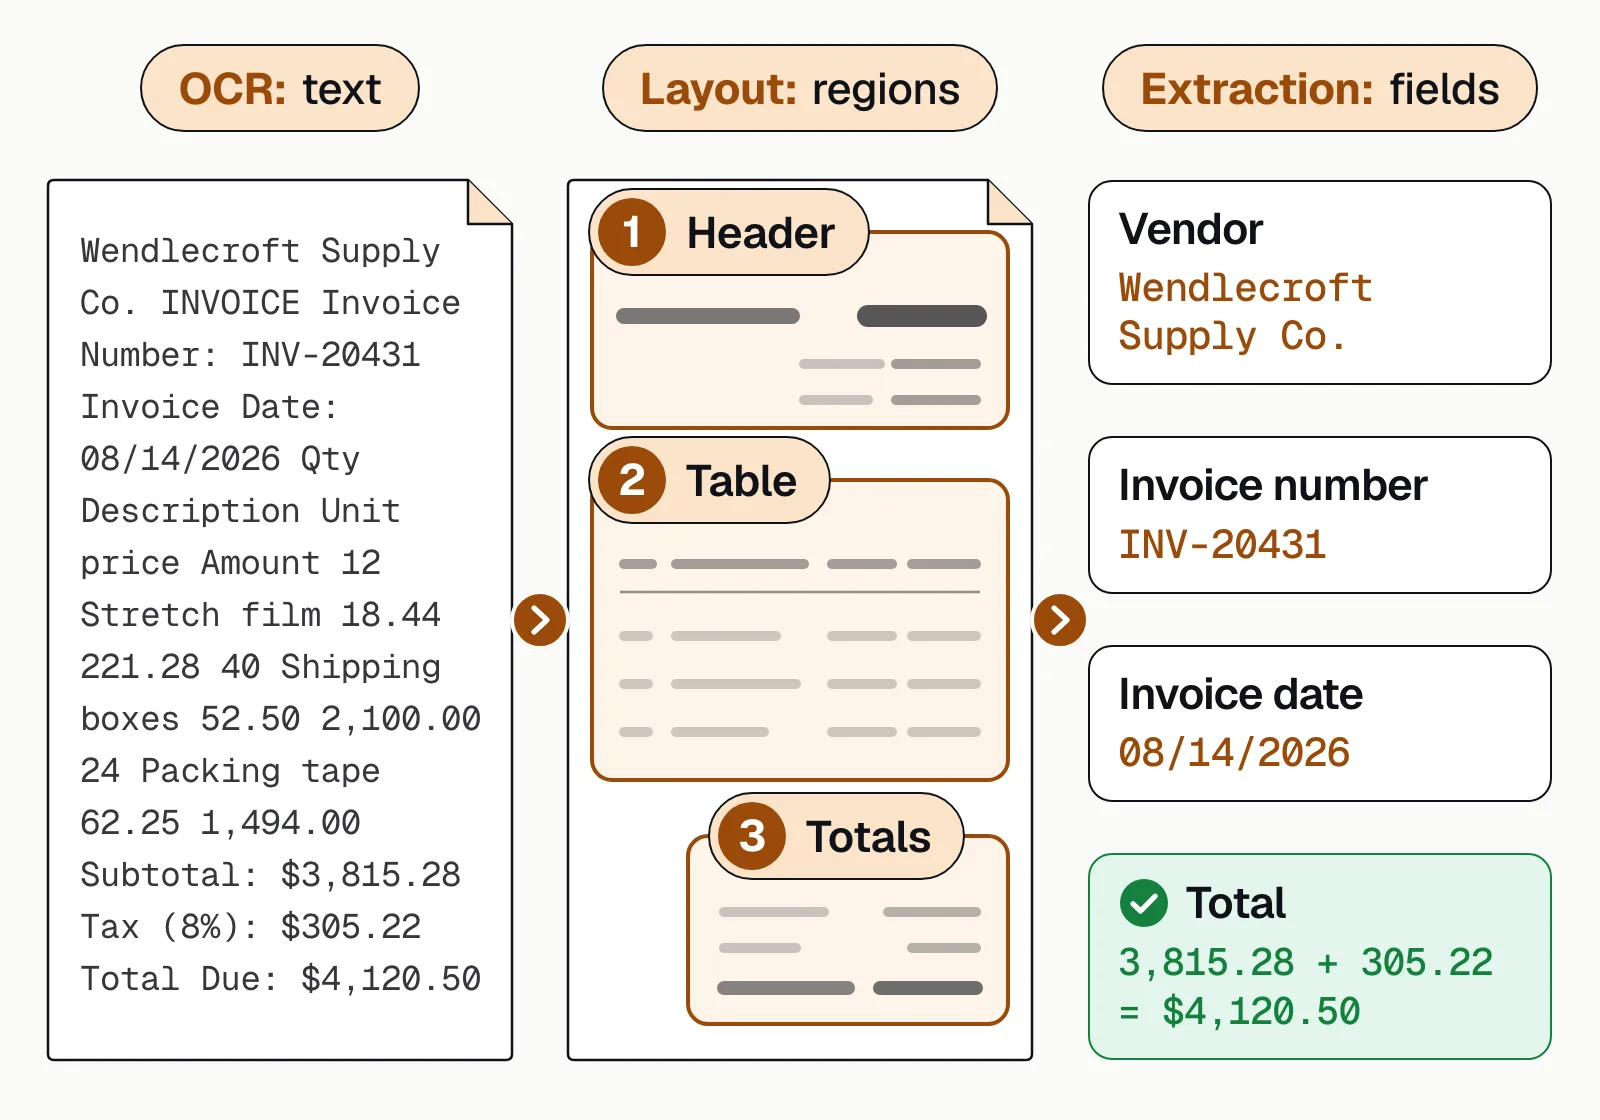
PDF was built to make a page look the same everywhere, not to make its data reusable. It stores characters and their positions, not "this is the invoice total".
Layouts vary
Every vendor, bank and manufacturer lays out invoices, statements and spec sheets differently.Scans have no text
A scanned PDF is a picture of the page. Nothing can be copied until OCR reads it.Structure is complex
Multi-column pages, nested tables, and tables that continue onto the next page.Volume breaks manual fixes
A process that works for 10 files a week breaks at 10,000.
A basic PDF parser returns the page's text in rough reading order, with nothing to say which value is which. Layout analysis and extraction turn it into fields.
First, check what kind of PDF you have#
Try selecting the text in a PDF viewer; what happens tells you the first step.
| PDF type | How to tell | First step |
|---|---|---|
| Native (digital) | Text selects and copies cleanly | Read the text layer; no OCR needed |
| Scanned | Nothing selects: the page is an image | Straighten and clean the page, then run OCR |
| Searchable scan | Text selects, but may copy with errors | Use the text layer; run OCR again where it's wrong |
| Fillable form | Fields you can click and type in | Read the field values directly |
To make a scanned PDF searchable, or to turn it into an editable Word file, a desktop OCR app is enough. See the best OCR software.
5 ways to extract data from PDFs#
How many PDFs, and how varied?
| Method | Works on | Accuracy | Effort at scale | Best for |
|---|---|---|---|---|
| Manual data entry | Anything | Varies with fatigue | High | A few documents a week |
| PDF converters | Text-based PDFs with simple layouts | Good on clean files; loses structure on complex ones | Medium (cleanup) | One-off conversions |
| Table extraction tools | Text-based PDFs with clear tables | Good on ruled tables | Medium | Statements and reports with regular tables |
| Rule-based templates | Fixed, known layouts | High on the layouts you built | High (a template per layout) | One form from one source |
| AI-based extraction | Any layout, native or scanned | High, with confidence scores | Low | Recurring documents in many layouts |
We wouldn't shortlist tools by whether they're marketed as OCR, document AI, document intelligence or an IDP platform, since those names all point at the same category. We'd rather take two or three candidates and run them on our own invoices, statements or forms to see which one actually gets the fields right without days of setup.
1. Manual data entry
Someone reads each PDF and types the values in. It takes no setup, but is slow and error-prone at volume.
2. PDF converters
Adobe Acrobat Pro and similar tools turn a whole PDF into Excel or Word. Complex layouts come out with split cells and merged columns.
3. PDF table extraction tools
Open-source libraries such as pdfplumber, Camelot and Tabula return a PDF's tables as rows and columns. This pulls the transactions from a text-based bank statement (tested on Python 3.11 with pdfplumber 0.11.10; pip install pdfplumber).
import pdfplumber

with pdfplumber.open("statement.pdf") as pdf:
    for page in pdf.pages:
        for table in page.extract_tables():
            header, *rows = table
            for row in rows:
                print(dict(zip(header, row)))
Output:
{'Date': '07/02/2026', 'Description': 'Payroll deposit', 'Amount': '2,450.00'}
{'Date': '07/05/2026', 'Description': 'Rent payment', 'Amount': '-1,800.00'}
{'Date': '07/19/2026', 'Description': 'Card purchase', 'Amount': '-86.40'}
It works because the table has ruling lines and a text layer. For scans and tables that run across pages, see table extraction from PDF.
4. Rule-based templates
A template reads each field from a fixed spot on a known layout, such as the value to the right of "Total Due". Every new layout needs a new template; see zonal OCR.
5. AI-based (intelligent) PDF extraction
Models trained on many examples find fields from text, layout and visual cues, so a new layout usually needs no setup. They read scans, join tables across pages and give every value a confidence score.
How to convert PDF data to Excel or Google Sheets#
| Destination | How | Good to know |
|---|---|---|
| Excel, one file | In Excel for Windows: Data > Get Data > From File > From PDF, then pick the tables | You get whole tables; similar tables on consecutive pages are joined by default |
| Google Sheets | Get the tables into Excel or CSV, then File > Import in Sheets | Sheets can't import a PDF, and Google Docs' OCR usually misses tables |
| Excel, every day | An extraction tool exports just the fields and line items you need from each new PDF | Suits recurring invoices and statements; Docsumo downloads extracted data to Excel |
For bank statements, see how to convert PDF bank statements to Excel.
How to extract pages from a PDF#
Extracting pages copies the pages you pick into a new PDF; it doesn't pull out the data on them.
| Tool | How |
|---|---|
| Adobe Acrobat | All tools > Organize Pages, select the pages, then Extract. Adobe's free online tool does the same for PDFs of up to 500 pages, after you sign in |
| Preview on a Mac | View > Thumbnails, then drag the pages from the sidebar to the desktop to make a new PDF |
In Python, pypdf copies a range of pages into a new file (tested with pypdf 6.19).
from pypdf import PdfWriter

writer = PdfWriter()
writer.append("packet.pdf", (2, 5))  # pages 3 to 5; numbering starts at 0
writer.write("pages-3-to-5.pdf")
For PDFs that hold several documents, such as a loan packet, classification and splitting cut the file where each document starts and label each part. In Docsumo, auto-classification and splitting are on the Business plan.
Common PDF extraction failures and fixes#
| Problem | Fix |
|---|---|
| Poor, skewed or rotated scans: OCR misreads characters or reads lines out of order | Straighten and clean the page first; send low-confidence values to review |
| Broken text layer: old or badly made PDFs return scrambled characters | Use OCR wherever the text layer is clearly wrong |
| Multi-column pages: text from both columns interleaves | Read each column as its own region |
| Complex tables: merged cells scramble columns, and rows break at page ends | Detect tables visually, drop repeated page headers and join the parts |
| Silent failures: a few files return wrong values nobody notices | Validate every result; route low-confidence values to a person |
How to automate PDF data extraction#
Automated PDF processing runs the same steps on every file, from intake to export. Automated document processing covers it in depth.
- Native PDFs
- Scanned PDFs
- Email attachments
- API uploads
- 01Classify each document
- 02OCR where there's no text
- 03Extract fields and tables
- 04Validate and review
- Pick the documentsStart with your highest-volume type, such as invoices or bank statements.
- Define the fieldsList what you need, including tables, and the format for each.
- Connect intakeUploads, an API or a shared inbox, depending on how the PDFs reach you.
- Extract and validatePre-trained models where they exist; rules and custom models for the rest.
- Review exceptionsA person checks only low-confidence or failed fields, each shown on the PDF.
- ExportDownload to Excel, or send results to your ERP or loan system through an API and webhooks.
Checks to run on extracted PDF data#
These checks catch most errors before they reach your systems.
- Totals add upLine items and tax sum to the total; transactions reconcile to the closing balance.
- Required fields are presentEvery field your system needs, in the right format.
- Dates are validThey parse, fall in a sensible range and run in order.
- Names match your recordsVendor, customer or account details agree with your master data.
- Uncertain values were reviewedAnything below your confidence threshold went to a person first.
In Docsumo, fields below your confidence threshold go to a reviewer, who clicks a field to see its source line on the page, and you can add your own checks as workflow steps, either an AI step or your own Python code. Try it free for 14 days on up to 1,000 pages; see pricing.
- 99%field-level accuracy across 250+ document types
- 95%+of documents processed straight through, without manual review
The method that survives at your volume#
Copy, convert or a table tool works fine for a handful of files. Once PDFs arrive every day in a mix of layouts and scans, and the numbers have to be right, that approach stops scaling and AI-based extraction with validation and review takes over. The best AI data extraction software compares the tools.
Book a demo with a few of your own PDFs, or start a free trial.
Frequently asked questions#
How do I extract data from a PDF into Excel?
In Excel for Windows, choose Data > Get Data > From File > From PDF, pick the tables you want and load them. For documents that arrive every day, such as invoices or bank statements in many layouts, use an extraction tool that pulls out the fields you need and exports them to Excel.
How do I convert a PDF to Google Sheets?
Google Sheets can't import a PDF. It imports Excel, CSV, TSV, text and OpenDocument files. Get the PDF's tables into Excel or CSV first, then use File > Import in Sheets. Opening the PDF with Google Docs runs OCR, but Google says tables aren't likely to be detected.
Can you extract data from a scanned PDF?
Yes, but it needs OCR (optical character recognition) first. A scanned PDF is only an image of the page, and OCR turns that image into text you can select, search and copy. After OCR, you still need rules or a model to find the specific fields.
How do I extract pages from a PDF?
In Adobe Acrobat, open All tools > Organize Pages, select the pages and choose Extract. On a Mac, drag page thumbnails from Preview's sidebar to the desktop to make a new PDF. To split mixed files by document type automatically, see document classification.
What is a PDF parser?
A PDF parser, or PDF scraper, reads a PDF's underlying elements and pulls out its text, fields, tables and images for reuse. Basic parsers return text; AI-based parsers also work out what each value means, such as which number is the invoice total.
How accurate is automated PDF data extraction?
It depends on document quality and variety, so test on your own files. Docsumo reaches 99% field-level accuracy across 250+ document types, and fields below your confidence threshold go to a person for review.
Sources
- Microsoft Support: Import data from data sources (Power Query), From PDF
- Microsoft Support: Power Query data sources in Excel versions
- Microsoft Learn: Pdf.Tables (MultiPageTables option)
- Google Docs Editors Help: Import data sets and spreadsheets
- Google Drive Help: Convert PDF and photo files to text
- Adobe: Learn Acrobat, how to extract pages from a PDF
- Adobe: Extract PDF pages online
- Apple Support: Add, delete or move PDF pages in Preview on Mac
- pypdf documentation: Merging PDF files
- pdfplumber on GitHub
- PyPI: pdfplumber
- Camelot on GitHub
- Tabula on GitHub
First published . Last updated .