IDP vs OCR: what's the difference, and which one do you need?
For operations, finance and IT leaders automating document work: how OCR and intelligent document processing differ, where document AI APIs and agentic processing fit, and how to decide which your documents need.

Key takeaways
- OCR converts an image of text into machine-readable text. It tells you what the characters are, not what they mean.
- Intelligent document processing (IDP) uses OCR as one step, then classifies documents, extracts named fields and tables, validates them, and sends exceptions to a person.
- OCR alone fits searchable archives and a few fixed layouts. IDP fits varied layouts, scans, multi-page tables and workflows where values drive decisions.
- Document AI APIs and agentic document processing extend the same line: the APIs extract fields from standard documents, while agentic systems run the whole workflow, checking documents against each other and routing only exceptions to people.
- Judge either by field-level accuracy and straight-through rate on your own documents, not by character accuracy on clean samples.
On this page
- What is OCR?
- What is intelligent document processing (IDP)?
- IDP vs OCR: side-by-side comparison
- How OCR and IDP handle common documents
- OCR vs IDP vs document AI vs agentic document processing
- Agentic IDP vs traditional OCR: what's the difference?
- Which one do you need?
- What each approach really costs
- The bottom line
- Frequently asked questions
IDP vs OCR comes down to what you get back. OCR (optical character recognition) converts an image of text into machine-readable text, while intelligent document processing (IDP) uses OCR as one step, then classifies the document, extracts named fields and tables, validates them and sends anything uncertain to a person. OCR gives you text; IDP gives you checked data you can act on.
This guide explains each, compares them side by side and against document AI APIs and agentic processing, and helps you decide which one your documents need.
What is OCR?#
OCR takes an image, such as a scan, a photo or an image-only PDF, finds the text on it and converts it to characters a computer can store and search. Modern OCR engines use neural networks that read whole lines at a time, and return the text with each word's position and a confidence score.
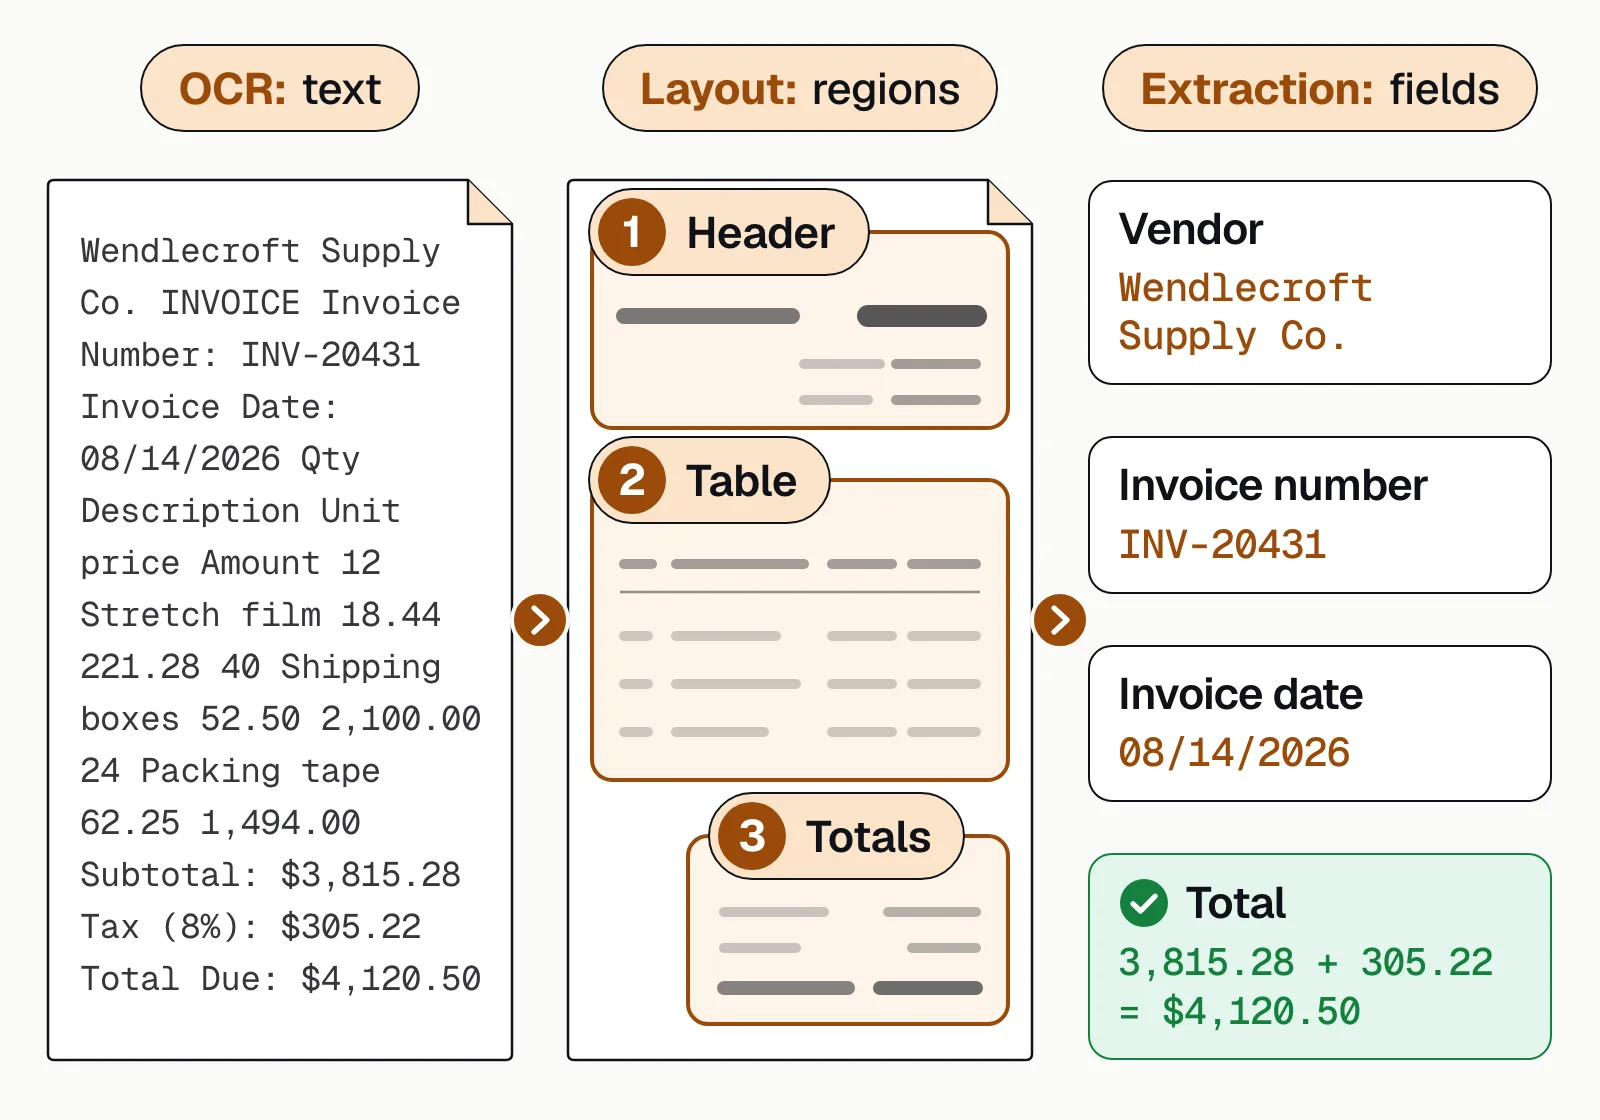
What OCR doesn't know is meaning: it returns "$4,120.50" but not that it's the invoice total. To get fields out of plain OCR, teams draw zones on a template for each layout (zonal OCR), and every new vendor, bank or form version needs a new template.
What is intelligent document processing (IDP)?#
IDP is a pipeline that turns documents from any channel into structured, validated data, with a confidence score on every value:
- Uploads
- Scans
- 01OCR
- 02Classify
- 03Extract
- 04Validate
- 05Review
Modern IDP uses large language models and vision models alongside OCR, so it can read layouts it hasn't seen before and pull fields a template couldn't. Docsumo, for example, reports 99% field-level accuracy on 250+ document types. See how that works in Docsumo Document AI.
IDP vs OCR: side-by-side comparison#
| Aspect | OCR | IDP |
|---|---|---|
| Output | Text, with positions | Named fields and tables, validated |
| New layouts | New template or rules for each layout | AI models read unseen layouts; fine-tune for your own |
| Document types | Doesn't know one document from another | Classifies and splits mixed files |
| Tables | Text lines; table structure often lost | Rows and columns kept, including multi-page tables |
| Validation | None; you build it | Rules within each document; some platforms also check across documents |
| Human review | You build it | Built-in review of low-confidence or failed values |
| Integration | Text files or an API you parse | Structured JSON through an API and webhooks |
| Best for | Search, archives, a few fixed layouts | High-volume, varied documents that drive decisions |
How OCR and IDP handle common documents#
A digital PDF invoice
OCR returns every word on the page; your code still has to find the vendor, dates, line items and total. IDP extracts the header and every line item, checks the lines add up to the total and flags duplicates. See invoice extraction.A scanned, handwritten form
OCR struggles with skew, handwriting and checkboxes. IDP straightens the page, reads handwritten fields and checkboxes, and sends low-confidence values to review with the source highlighted.A bank statement
OCR returns each page's text, with transaction rows split across lines and pages. IDP returns every transaction as one table and checks each row against the running balance. See bank statement extraction.A check
OCR reads the printed text and the MICR line, but handwritten amounts and payees are error prone. IDP reads the amount in figures and in words and flags a mismatch. See OCR vs MICR.
OCR vs IDP vs document AI vs agentic document processing#
Vendors often sell the same capability under four names, but they're stages of one line, not rival products. Document AI usually means a cloud API that extracts fields with pre-trained models (Google Document AI, Amazon Textract, Azure Document Intelligence); agentic document processing runs the whole workflow, including the checks between documents and the routing of exceptions to people.
| Dimension | OCR | IDP | Document AI API | Agentic |
|---|---|---|---|---|
| Output | Text | Validated fields | Fields from standard documents | Checked data, posted to your systems |
| Setup per document type | None, but no fields | Template or training, less with AI models | None for standard types; training for custom ones | None; new layouts handled on arrival |
| Checks across documents | No | Usually no | No; one document per call | Yes, across a whole file |
| Exceptions and review | You build it | Review queue for low-confidence values | You build it | Only exceptions, each with its reason |
| Where the cost sits | People turning text into data | Setup and template upkeep | Per page, plus the workflow you build | Rollout; manual work shrinks to exceptions |
Extraction itself is becoming a commodity: Forrester's Boris Evelson wrote in November 2025 that generative and agentic AI is becoming an equalizer that makes it harder for vendors to differentiate. For buyers, that means judging a platform on what happens around extraction, not on extraction alone.
Agentic IDP vs traditional OCR: what's the difference?#
A traditional OCR pipeline returns text and leaves the parsing rules, checks and review to your team. Agentic IDP plans and carries out those steps itself, checking related documents in the same file against each other (the income on a bank statement against the income on a tax return, say). Read more in what is agentic document processing.
Traditional OCR pipeline
- Returns a block of text per page
- A template or parsing rule for every layout
- Each document is read on its own
- A person checks every output
- Corrections fix one document and are forgotten
Agentic IDP
- Returns named fields and tables with a confidence score
- New layouts are read the first time they arrive
- Documents in a file are checked against each other
- Only exceptions go to review, each with the reason
- Reviewer corrections improve the model
Agentic doesn't mean no people: review narrows to uncertain fields and figures that don't reconcile, so be wary of any vendor that promises zero human review.
Which one do you need?#
Choose OCR for searchable text and a few layouts that never change. Choose IDP when the same documents arrive from many senders, people retype values into another system, or errors cost money.
Which fits your documents?
A quick test: count the hours people spend each week typing or checking values from documents. That's the work IDP takes on. On Docsumo's intelligent document processing platform, teams handle a document in under 5 minutes instead of 2 or more hours by hand, with 95%+ straight-through processing.
What each approach really costs#
OCR has the lower sticker price, but the work it leaves undone still has to be paid for. Count all of it before you compare:
- Per-page feesOCR API charges against IDP platform pricing.
- Exception laborHours spent reviewing, correcting and retyping, at your loaded labor rate. A small error rate across thousands of documents a day is hundreds of exceptions.
- Error costDuplicate payments, compliance findings and credit losses from values nobody checked.
- Template upkeepDeveloper time spent updating rules when a layout changes, and there are usually more layouts than anyone expected.
- Integration workCode that turns OCR text into records your systems accept.
- The rebuildScripts, rules engines and exception queues built around OCR that end up recreating an IDP platform.
Total cost per document
Per-page prices look small until you add the time people spend fixing what the tool gets wrong.
- Tool cost per month
- Review time per month
- Total per month
- Total cost per document
How it's worked out
- Tool cost = documents × pages × price per page.
- Review time = documents × the share reviewed × minutes per review ÷ 60 × hourly cost.
- Compare tools on the total per document, not the price per page: a cheaper tool that sends more documents to review can cost more.
Before you scale, pilot one high-volume workflow alongside your current process and measure straight-through rate, cycle time and cost per document. For what tends to go wrong, see IDP challenges.
The bottom line#
OCR reads characters; IDP reads documents: what they are, what fields they contain, whether the values make sense and where they need to go. If you need data you can act on, choose IDP, and if your documents arrive as files that must agree with each other, look for agentic processing with cross-document validation. Docsumo combines Document AI and document workflows that post results through an API and webhooks, with case management and cross-document validation on the Enterprise plan. For developer options, see our OCR API guide.
Book a demo with a few of your hardest documents, or start a free trial.
Frequently asked questions#
What is the difference between IDP and OCR?
OCR converts images to text. IDP turns documents into validated, structured data. It uses OCR to read the page, then AI models to classify the document, extract fields and tables, check them against rules and route anything uncertain for review.
Is IDP better than OCR?
For business workflows with varied documents, yes, because it returns usable fields rather than raw text. For simply making scans searchable, OCR is enough and cheaper.
Does IDP replace OCR, and is OCR becoming obsolete?
No to both. IDP includes OCR, or a vision model that does the same job, as its first step on scanned pages. OCR on its own still suits searchable scans and archives, while workflows that need validated data use it as one layer inside an IDP platform.
What is the difference between agentic IDP and traditional OCR?
Traditional OCR returns the text on a page and leaves parsing, checks and review to your team. Agentic IDP reads the document, extracts named fields without a template per layout, checks related documents against each other and sends only uncertain or mismatched values to a reviewer, with the reason.
Is document AI the same as IDP?
Partly. "Document AI" often means a cloud extraction API such as Google Document AI, Amazon Textract or Azure Document Intelligence. These extract fields from standard documents well, but the review queue, workflow and audit trail are yours to build, which an IDP platform includes.
Can OCR read handwriting?
Modern OCR engines read neat handwriting, but accuracy drops on messy handwriting, checkboxes and signatures. IDP platforms add models trained for handwritten fields and flag low-confidence values for review.