What is data extraction? Definition, types, methods and examples
For operations, finance and data teams: what data extraction means, which method fits which source, and how it works on a real invoice.

Key takeaways
- Data extraction pulls specific data out of a source, such as a database or a document, and saves it in a structured form.
- The term has two meanings. Data teams use it for copying records out of databases and apps, the E in ETL. Operations teams use it for reading fields off documents.
- Database extraction runs as a full or incremental copy. Documents differ by how structured they are, and each kind needs a different method.
- The main methods are manual entry, templates, rules, machine learning, LLMs, APIs and web scraping, and most document pipelines combine several.
- Document extraction pays off only with validation. Checks that totals add up and that values match other documents catch errors before they reach your systems.
On this page
- What is data extraction?
- Two meanings: databases and documents
- Structured, semi-structured and unstructured sources
- Data extraction methods
- Worked example: data extraction from one invoice
- Manual vs automated data extraction
- How to extract data from documents
- Data extraction vs ETL, scraping, parsing and mining
- Data extraction examples by team
- Common data extraction challenges
- How to choose a data extraction approach
- If someone on your team still copies data out of PDFs
- Frequently asked questions
Data extraction means pulling specific data out of a source and saving it in a structured form. The source can be a database, an app, a website or a document such as an invoice. Once each value sits in a named field, software can store it, move it or analyze it.
It's the first step in most data work, because you can't report on data or act on it until you get it out. A data engineer and an AP clerk mean different things by the term. The sections below cover both, then follow one invoice from scan to finished record.
What is data extraction?
Extraction is selective. You pull the fields you need, such as an invoice number and its total, not the whole file. It's also structured. Each value lands in a named field that software can use, such as a column in a table or a key in a JSON record.
Copying a file isn't extraction, and neither is reading a page. A scanned invoice holds its total, but no system can use that total until it sits in a field called total. Errors at this step carry through to everything downstream. A misread total becomes a wrong payment, and a missed transaction becomes a wrong income figure.
Two meanings: databases and documents
In data engineering, data extraction means copying records out of databases, apps and other source systems so they can be loaded somewhere else. It's the E in ETL, which stands for extract, transform, load. The data is copied to a staging area, cleaned and reshaped, then loaded into a warehouse or business system. ELT changes the order. It loads the raw data first and transforms it inside the warehouse.
In operations, data extraction means reading documents and pulling out the fields a process needs. Invoices, bank statements, pay stubs, tax forms and claim forms all carry data that someone has to get into a system. Here the data isn't structured yet. A person or a program has to find the invoice number on the page before it can go anywhere.
The two meanings connect. Data pulled from documents often becomes one more source for an ETL pipeline. The rest of this page focuses on documents.
Full and incremental extraction
When the source is a database, extraction runs in one of two ways. A full extraction copies all the data each time, so nothing has to track what changed. An incremental extraction copies only the data that changed since a set point, such as the last run. To find those changes, each row needs a last-changed timestamp, or the system keeps a separate record of changes. This approach is often called change data capture (CDC).
Documents work differently. Each new file is a fresh extraction, so the question is how to read it, not what changed.
Structured, semi-structured and unstructured sources
How structured the data is decides how you extract it.
Structured
Databases, spreadsheets and APIs. Queries and ETL tools copy the rows and columns you need.Semi-structured
Invoices, bank statements, pay stubs and forms. Each one has the same fields, but every sender puts them in a different place. OCR plus AI models find them.Unstructured
Contracts, letters, clinical notes and scans. OCR plus language models find the facts in free text.
More in our guide to structured, unstructured and semi-structured data.
Data extraction methods
Most extraction uses one of these methods, or a mix of them.
| Method | How it works | Works well for | Falls down on |
|---|---|---|---|
| Manual entry | People read each value and type it in | Small volumes, one-off tasks | Speed, cost and typing errors |
| Templates and zonal OCR | Read fixed zones on a known layout | A few forms that never change | Every new layout needs a new template |
| Rules and regular expressions | Find values by pattern, such as dates, amounts and IDs | Predictable formats, and checking values | Wording that varies from sender to sender |
| Machine learning models | Learn where fields sit from labeled examples | Many layouts of one document type | Needs labeled examples for each type |
| LLM-based extraction | A language model fills in a schema you give it | New layouts and free text, with no training | Can return a confident wrong value |
| APIs and connectors | Ask the source system for the data, usually as JSON | Apps and databases that expose the data | Only covers what the API exposes |
| Web scraping | Parse a web page's HTML for the values | Public sites with no API | Breaks when the page changes; check the site's terms |
| Intelligent document processing (IDP) | OCR plus AI models classify, extract and validate | Many layouts at high volume | Needs a pilot on your own documents |
OCR isn't on the list because it doesn't pull out fields by itself. It turns a page image into text, and another method still has to find the invoice total in that text. Zonal OCR and LLMs in document processing go deeper on two of these methods.
Most document pipelines combine methods, which is what intelligent document processing platforms do. For 10 techniques side by side, with a code example, see data extraction techniques.
Worked example: data extraction from one invoice
Take one invoice from a supplier, Wendlecroft Supply Co., that arrives as a scanned PDF. Its data has to reach the AP system before anyone can approve it.
First, OCR turns the image into text. The result is one long run of words and numbers, with nothing to say which number is the total. Next, layout analysis finds the header, the line-item table and the totals, the same three regions a person spots by eye.
Then extraction names each value. The vendor is Wendlecroft Supply Co., the invoice number is INV-20431 and the invoice date is 08/14/2026. The table gives three line items, such as 40 shipping boxes at $52.50 each, for $2,100.00.
Last, validation checks the math. Each line's quantity times its unit price must equal its amount. The three amounts must add up to the $3,815.28 subtotal, and the subtotal plus $305.22 of tax must equal the $4,120.50 total. If OCR had misread one digit, a check would fail and the invoice would go to a person instead of straight to the AP system.
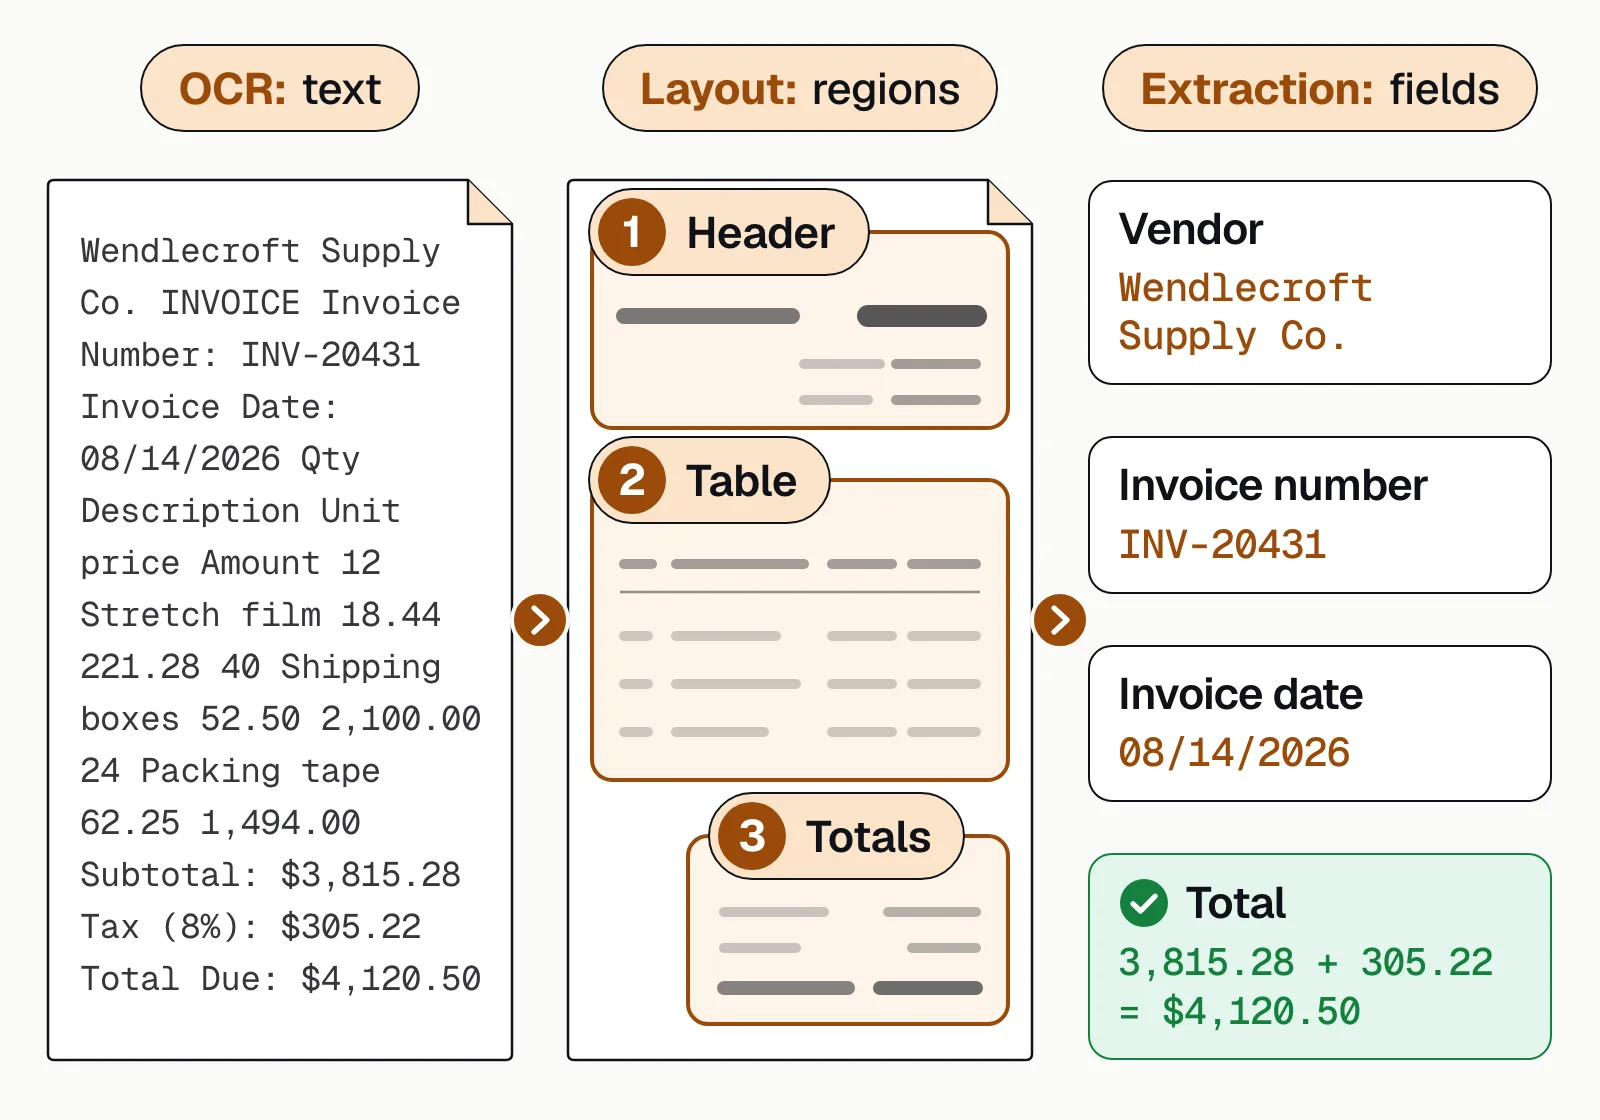
The output is a record any system can read. The date is rewritten in the standard year-month-day form (ISO 8601).
{
  "vendor": "Wendlecroft Supply Co.",
  "invoice_number": "INV-20431",
  "invoice_date": "2026-08-14",
  "line_items": [
    { "quantity": 12, "description": "Stretch film", "unit_price": 18.44, "amount": 221.28 },
    { "quantity": 40, "description": "Shipping boxes", "unit_price": 52.50, "amount": 2100.00 },
    { "quantity": 24, "description": "Packing tape", "unit_price": 62.25, "amount": 1494.00 }
  ],
  "subtotal": 3815.28,
  "tax": 305.22,
  "total": 4120.50
}
For the fields AP teams pull from invoices, and how to automate them, see invoice data extraction.
Manual vs automated data extraction
Manual extraction makes sense for small volumes. As volume grows, automation turns typing into checking.
Manual: typing
- People key every value from every document
- Typing errors slip through unnoticed
- Work backs up at month-end and tax season
Automated: checking
- Software reads each document and fills the fields
- Totals and formats are checked automatically
- People review only the values the software is unsure of
Here's what that looks like on Docsumo.
- 99%field-level accuracy across 250+ document types
- 95%+of documents AI Approved, with no manual review
- <5 minper document, down from 2+ hours
How to extract data from documents
Six steps take a document from arrival to your systems. The block below shows step 3 on a business bank statement.
| Field | Extracted value | Confidence |
|---|---|---|
| Account holder | Harbor Street Bakery LLC | |
| Address | 118 Harbor St, Portland, ME | |
| Bank name | First Midwest Bank | |
| Account number | •••• 4821 | |
| Account type | Business checking | |
| Statement period | 2026-07-01 → 2026-07-31 |
| Field | Extracted value | Confidence |
|---|---|---|
| Opening balance | 42,180.55 | |
| Total deposits | 88,412.10 | |
| Total withdrawals | 91,686.44 | |
| Closing balance | 38,906.21 | |
| Transaction count | 142 |
| Field | Extracted value | Confidence |
|---|---|---|
| Date | 2026-07-14 | |
| Description | ACH DEPOSIT STRIPE PAYOUT | |
| Amount | +3,284.10 | |
| Debit / credit | Credit | |
| Running balance | 51,902.44 | |
| Category | Card processor payout |
- CollectRoute email, uploads, scans and API submissions into one queue.
- Classify and splitIdentify each document and split combined PDFs, such as a loan packet.
- ExtractCapture every field and table row with a model trained on that document type, such as bank statements or invoices.
- ValidateCheck totals and formats, and compare documents. Does pay stub income match the deposits on the bank statement?
- Review exceptionsSend only low-confidence values to a person, with the source highlighted.
- ExportPush the data to your systems by API or webhook, or as Excel, CSV or JSON.
Data extraction vs ETL, scraping, parsing and mining
Several terms sit close to data extraction, and people often mix them up. Here's how each one relates.
| Term | What it does | How it relates to extraction |
|---|---|---|
| ETL and ELT | Extract data, transform it and load it into a warehouse or system | Extraction is the first step |
| Data ingestion | Moves data from its sources into a destination | Extraction decides what to pull out. Ingestion gets it to where it's used. |
| Web scraping | Collects data from web pages by parsing their HTML | One kind of extraction, for websites |
| Data parsing | Breaks raw input into parts and maps them to fields | A step inside most extraction, after the text is read |
| Data mining | Finds patterns in data that's already collected | Comes after extraction and works on its output |
People sometimes say "mining" when they mean extraction, but mining is analysis. For more detail, read data extraction vs data scraping, data extraction vs data ingestion, which also covers ETL, and our guide to data parsing.
Data extraction examples by team
Document extraction is common wherever a decision depends on documents.
Finance and accounts payable
Invoice headers, line items and PO numbers for invoice matching and approval.Lending
Bank statements, pay stubs, tax returns and IDs for income verification and underwriting.Insurance
ACORD forms, loss runs and certificates of insurance for underwriting and compliance.Healthcare
CMS-1500 and UB-04 claim forms, EOBs and medical records for healthcare billing and records review.Commercial real estate
Rent rolls and operating statements for property underwriting.Logistics
Bills of lading, delivery notes and customs documents for billing and freight audit.
BCG, the Mortgage Bankers Association and AARMR surveyed 31 mortgage lenders and servicers in 2026. Of those, 61% had AI data extraction from documents in production, the most common AI use in making new loans (BCG, MBA and AARMR, 2026).
In finance, Gartner surveyed 160 senior finance leaders from January to April 2026. It found that data extraction generally delivers returns within 9 to 10 months, as do AP and AR automation and report creation (Gartner, 2026).
Common data extraction challenges
Each has a fix you can test before you buy.
- Varied layoutsEvery bank and vendor formats documents differently. Use models that find fields from context, not templates.
- Poor scansSkewed pages, faxes and photos cause misreads. Flag low-confidence values for a person.
- Tables across pagesLine items that span pages come apart. Check they come out as one table.
- Handwriting and checkboxesNot every OCR engine reads handwriting or checkbox marks. Test tools on your own handwritten samples.
- Silent errorsA misread digit still looks valid. Check totals and compare values across documents.
- SecurityFinancial and health documents carry personal data. Choose a vendor with SOC 2 Type 2, HIPAA and GDPR coverage.
How to choose a data extraction approach
Start with where the data lives, then let volume and the number of layouts decide.
If the data sits in a database or an app, you don't need document tools. Query it with SQL or call the app's API, and let an ETL tool run the job on a schedule.
If it's on public web pages with no API, scrape it. Check the site's terms first, and expect to fix the scraper when the page changes.
If it's in documents, count the layouts. One form that never changes can run on a template or a few rules. Invoices from every supplier, or statements from every bank, need models or LLMs that find each field from its context.
Then decide how errors get caught. Look for a confidence score on every value, checks that totals add up, and a review screen for the values the software isn't sure of. If a decision depends on several documents agreeing, as in a loan file or a claim, check whether the tool compares documents with each other.
Our take. Don't try to automate every document type at once. Pick the one that arrives in volume and that a decision depends on. Bank statements in a loan file and invoices waiting for approval are good examples. Get that one reading and checking well, then add the next.
If someone on your team still copies data out of PDFs
Databases and APIs are the easy part of data extraction. Documents are where teams still type by hand, and where AI extraction with a review step saves the most time. To compare tools, see the best data extraction software, or read how automated data extraction works end to end.
Book a demo with a few of your own documents, or start a free trial.
Frequently asked questions
What is data extraction in simple terms?
It means taking the information you need out of wherever it lives, such as a PDF, a database or a web page. You then save it in a form software can use, like a spreadsheet row or a JSON record.
What are the types of data extraction?
For databases there are two. A full extraction copies all the data each time, and an incremental extraction copies only what changed since the last run. Sources are also grouped as structured, semi-structured or unstructured.
What is an example of data extraction?
A lender reads a borrower's bank statement and pulls the account holder, balances and every transaction into its underwriting system. An AP team does the same with the vendor, invoice number, line items and total on each invoice.
What is the difference between data extraction and data mining?
Extraction retrieves data from a source. Mining analyzes data that's already collected to find patterns. Extraction usually comes first. See data extraction techniques.
Is data extraction the same as web scraping?
Web scraping is one kind of data extraction, specific to websites. Data extraction also covers databases, apps, files and documents. See data extraction vs data scraping.
What tools are used for data extraction?
ETL and ELT tools pull data from databases and apps, and scraping tools pull it from websites. For business documents, intelligent document processing reads each page, pulls out the fields and checks them.
Sources
- IBM: What is ETL?
- Oracle Database 19c Data Warehousing Guide: Extraction in Data Warehouses
- BCG, MBA and AARMR: The state of AI among mortgage lenders and servicers (September 2026)
- Gartner: CFOs must take a more disciplined approach to finance AI investment (September 2026)
First published . Last updated .